AI-XDLC. Running a design lifecycle with an AI agent that knows when to stop.
About this project
AI-XDLC adapts the staged, verifiable, human-governed lifecycle of AI-DLC to design work. This case study is about the runner I designed and built for it, and what the build taught me about where humans belong in an AI design process. The screens use a fictional news-app feature as the worked example.
Challenge
Every AI design tool I tried optimised for the same moment: prompt in, screens out. That is the least interesting part of design work and the easiest to get wrong. What I wanted was the rest of the process: clarifying intent, grounding in context, generating options, checking them against explicit criteria, and stopping when a decision needed a human. I had the methodology written down as rules. What I did not have was a way to run it that made the gates as visible as the output.
Strategy
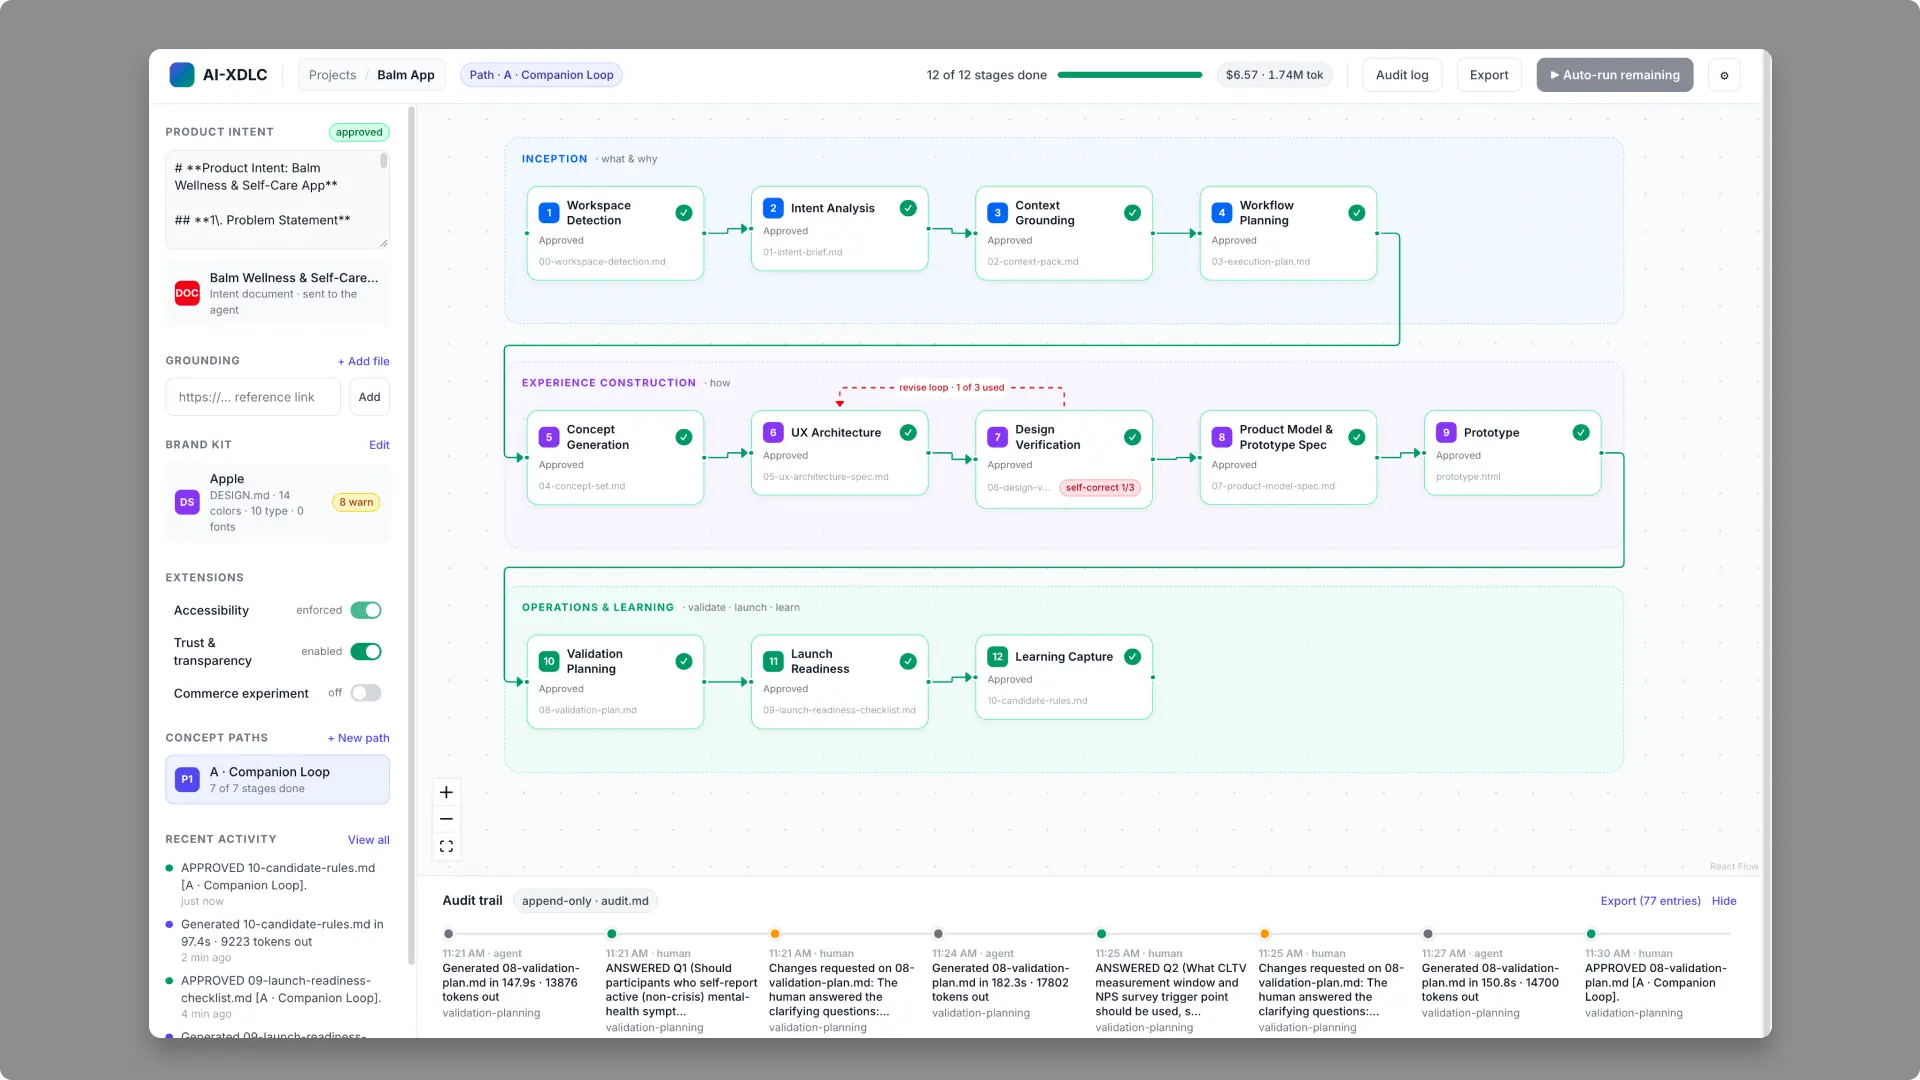
Treat the methodology as the product. Twelve stages, three phases, and a rule file for each stage became nodes on a canvas, laid out left to right in phase lanes. A node is locked until the one before it is approved. Every artifact the agent produces pauses at a gate: approve, request changes, pick a direction, or resolve a finding.
The agent runs the loop the methodology prescribes: generate, verify, self-correct, halt or escalate, learn. Design Verification is the hinge. The agent reads its own report as structured findings, revises the target artifact for anything blocking, re-verifies, and gives up after three attempts. Anything that needs editorial, legal, brand, or strategic judgment is escalated to me as a decision with options and a required rationale.
Everything else is grounding: an intent brief, references, a DESIGN.md brand kit whose tokens flow into specs and get injected into prototypes as CSS, and my own answers to the agent's clarifying questions, carried forward as facts. The app is a static site. Claude is called from the browser with my own key, projects live in the browser, and an optional Netlify Blobs sync keeps them across devices.
Results
A working runner that takes a product intent through twelve gated stages to a verified spec, a validation plan, a self-contained HTML prototype, and a set of candidate rules learned from the run. Every action, including the autonomous ones, is in an append-only audit log, and every API call is metered so the cost of a self-correction loop is visible in dollars, not just tokens. The design came first: a Figma stage map of the methodology, a worked example, and the UI the app follows. The app went from that design to a running build in a day, and the rule files are bundled verbatim into every prompt, so the tool and the method cannot drift apart.
The story
AI-XDLC started as a document: a methodology for letting an agent do design work inside explicit guardrails, with human approval at every step that matters. The document was fine. Nobody, including me, was going to run it by hand. So I built the thing that runs it.
The most interesting design move was making decisions the primary interaction. Most AI tools put the output in the centre and the controls at the edge. Here the canvas shows state, not content: which stage is approved, which is waiting on me, where a revise loop has run. The artifact lives in a panel you open when you want to read it. The thing you cannot avoid is the decision. In the worked example, an AI-generated daily brief for a news app, verification found that AI summaries carried the same visual weight as the editor's lead story, fixed it on its own, and then stopped on the question of consent for personalised recommendations. That is the split I wanted. The agent handles the checkable. I handle the judgment.
The second move was turning prose into data the app can act on. The methodology speaks in markdown: clarifying questions in a fixed format, findings with severities, concept sets with a recommendation. The runner asks the agent to append small machine-readable blocks alongside the prose, then parses them into questions I can answer with a click, findings with waive and decide actions, and concept options that spawn a path. The prose stays the artifact; the data drives the interface. The same idea runs through the brand: a DESIGN.md file is both the rulebook the agent reads and the token source the prototype is built from.
The third move was refusing to hide cost and time. Every call is logged with its model, tokens, duration, and reason: generate, self-correction two, re-verify one. The top bar shows the running total. A three-attempt correction loop is honest about what it costs, and that changes how you set the limits. It also surfaced a real behaviour: answer the agent's questions and it will happily ask new ones, some earned by your answer and some because the section exists. Deciding when to stop asking is a design decision too.
What the build proves is smaller than it sounds and more useful. You do not need an orchestration platform to run a governed AI process. You need explicit post-conditions, a place where the agent must stop, and a record of what happened. The hard part was not the API calls. It was deciding which decisions are mine.
Select highlights
- Turned a written methodology into a runnable canvas: twelve stages, three phases, every rule file injected verbatim into the agent's prompts.
- Built the verify, self-correct, escalate loop for real: blocking findings are fixed by the agent within three attempts; judgment calls stop for a human with options and a rationale.
- Made the agent's clarifying questions answerable: questions become decision cards, and answers flow to every later stage as facts.
- Adopted DESIGN.md as the brand input, with a browser-side lint and tokens injected into prototypes as CSS variables and embedded fonts.
- Shipped it as a static app with browser-direct Claude calls, an append-only audit trail, and per-call cost tracking. Source on GitHub.